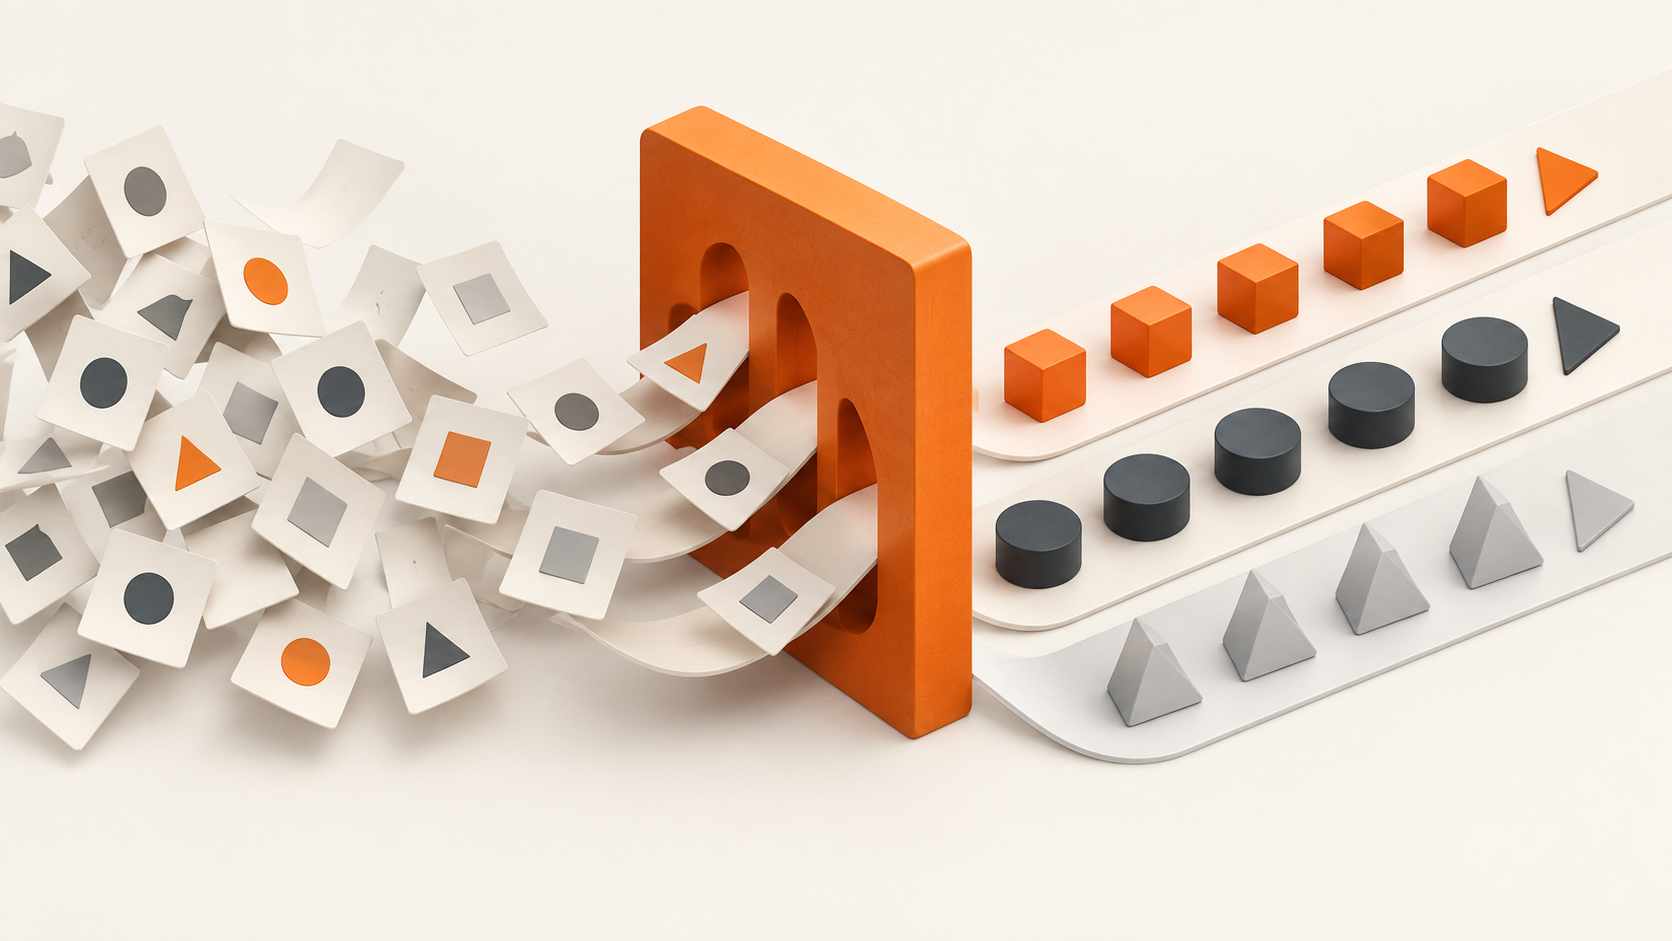
Jev by TypeSafe AI is a model that helps software make structured decisions: which team should handle a request, how relevant a document is, or whether a message needs urgent attention. Instead of writing a response, it evaluates the context you provide and returns results your code can use.
For developers building AI agents, that makes Jev worth exploring for routing, classification, and scoring. This guide explains how it differs from a generative model, walks through its Choice, Score, and Noul question types, and shows a small API example you can use as a starting point.
What is Jev by TypeSafe AI?
TypeSafe introduced Jev on September 15, 2026. It accepts contextual state and predefined questions, then returns typed results instead of open-ended prose. The company positions it for repeated judgments inside software. See the official launch announcement, rather than relying on similarly named community sites.
The useful distinction is the interface. You define the possible outcomes before the request. Your application receives values it can route on, while ordinary code retains responsibility for permissions, thresholds, and execution.
TypeSafe's headline speed and cost comparisons describe its own evaluation workloads. They are not a prediction for every application. Measure the complete path you intend to ship, including retrieval, network time, retries, and any follow-up model call.
Jev vs an LLM: which agent steps fit?
A useful first experiment is to inspect your existing agent trace. Look for calls whose entire useful output is a category, a ranking, or a yes-or-no judgment. Keep free-form drafting and open-ended problem solving with a generative model. LangChain's Jev integration guide describes this complementary approach.
| Workflow step | Suitable approach | What your application consumes |
|---|---|---|
| Select one of several support queues | Jev Choice | An allowed option and its distribution |
| Rate an item against ordered criteria | Jev Score | A numeric assessment and uncertainty |
| Check whether a message expresses urgency | Jev Noul | A probability between zero and one |
| Write a personalized response | Generative model | New text |
| Calculate an invoice total | Deterministic code | An exact calculation |
| Execute a selected data lookup | API client | The endpoint's response |
This division also makes debugging easier. If a result is wrong, you can investigate whether the source data was incomplete, the question was ambiguous, or the execution logic mishandled a valid answer. A single model call doing everything obscures those distinctions.
Understanding Choice, Score, and Noul
TypeSafe documents three primitives in its introduction. Each describes a different shape of decision.
Choice selects from named options. For example, route an incoming request to research, support, or manual review. Give each option a distinct description. Include an escape route when your categories cannot cover every possible request.
Score evaluates an ordered rubric. Define what the levels mean, rather than asking for an unexplained quality number. Separate relevance and completeness into different questions if they influence different downstream actions.
Noul estimates whether a statement is true on a zero-to-one scale. It fits checks such as whether supplied text contains an explicit deadline. It is a probability, not a Boolean that should automatically be cast to true whenever it is nonzero.
Choice and Score include confidence; Noul does not expose the same confidence field. TypeSafe's confidence documentation also distinguishes an option's probability from the confidence statistic derived from the distribution. Do not interchange those values in your routing code.
Try a small Jev API request
Start with a request that has one clearly defined purpose. The following example follows the official HTTP quickstart. Set TYPESAFE_API_KEY in your environment using a key from your TypeSafe account.
curl --fail-with-body --max-time 30 \
  https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  --data-binary @- <<'JSON'
{
  "model": "jev-latest",
  "state": "Our checkout stopped working this morning. Customers cannot place orders.",
  "questions": {
    "urgent": {
      "type": "noul",
      "instructions": "Does this message describe an active problem preventing customers from purchasing?"
    }
  }
}
JSON
Read the probability from answers.urgent.noul. The request format was checked against the documentation; this example was not executed against a paid account. No response value is fabricated here.
For an initial trial, log the result alongside a human label instead of letting it trigger an action. Review disagreements, refine the question, and then decide which cases can safely be automated. Handle HTTP failures separately from uncertain model answers.
Where AIsa fits in a Jev workflow
Consider a research agent that sorts incoming questions before collecting evidence. Jev can evaluate a routing question; your application can then call the selected search or data service. AIsa provides access to external APIs and model capabilities through a unified gateway, as described in its documentation.
A proposed implementation would collect the user's request, ask Jev which predefined research category fits, validate the result, then call an appropriate endpoint from the AIsa API catalog. A generative model could summarize the returned evidence afterward. This is an architecture suggestion, not a claim of a built-in Jev integration or Jev availability through AIsa.
Keep the model's options mapped to an allowlist of functions. A returned label should select reviewed application code, not become an arbitrary URL or shell command. Add request budgets and record which evidence informed each decision.
Five practical tips for Jev agent workflows
- Start with one bottleneck. Replace a narrow classification step and compare it with the existing workflow before redesigning your whole agent.
- Make categories distinguishable. Test ambiguous examples, not just obvious ones. Overlapping labels make evaluation difficult.
- Create a review path. Decide what happens when evidence is missing or the model is uncertain before enabling automatic execution.
- Measure useful outcomes. Track incorrect routes and review volume alongside latency. A faster mistake is still a mistake.
- Retest after changes. Keep a representative evaluation set and rerun it when instructions, model versions, or incoming data change.
Five terms to know when evaluating Jev
- State: The context supplied for evaluation, such as a customer message and relevant account details.
- Typed output: A result constrained to an expected structure or allowed value. This constrains format, not factual truth.
- Probability distribution: The probabilities assigned across possible outcomes, rather than only the selected label.
- Calibration: Agreement between predicted probabilities and observed outcomes across many examples, not proof that any single prediction is correct.
- Agent harness: The application code coordinating model calls, tools, state, and execution rules around an agent.
Watch a Jev classification walkthrough
It is a relevant companion for exploring Jev as a classifier. Use the current official documentation for request details, since early demonstrations can age quickly.
FAQ: Jev by TypeSafe AI
What is Jev AI used for?
Jev targets bounded judgments such as classification, routing, and rubric-based scoring. The best starting point is a task whose permitted outcomes you can define clearly and evaluate against real examples.
Is Jev a replacement for a chatbot?
No. Its structured decisions serve a different purpose from conversational responses. Keep a generative model where the application needs explanations, drafts, or other new text.
Can Jev make incorrect decisions?
Yes. Jev can return a valid option and still make the wrong judgment. Test it on real examples from your workflow, and send uncertain or consequential decisions for human review.
What does Jev confidence tell me?
For Choice and Score, it summarizes how concentrated the probability distribution is. It is useful for routing policy, but you should choose thresholds using your own evaluation data and error costs.
How should I start using Jev with AIsa?
Use TypeSafe's documented interface for the decision step and AIsa's documented endpoints for relevant data or model calls. Start with a read-only workflow and inspect each stage before adding automated actions.
Ready to build the execution side? Browse the AIsa API catalog, choose one relevant capability, and connect it to a small, measurable decision workflow.